
Night shift: a local Gemma writes my 7 a.m. lab report, and I measured where it makes things up
What happened in the lab overnight? Most mornings the answer is nothing, and finding that out still means opening logs. Some mornings it is something, and logs are a slow way to find out.
So I built a night shift. Two small machines send a heartbeat all night, fixed rules go over the night at 6:30 a.m., and before 7 each machine leaves a short report written by Gemma 3, running on the machine itself, with no internet and no API key. The lazy part: nobody has to read logs in the morning. The careful part: I did not hand the model that job until I had measured where it gets things wrong.
What I built
The lab is an Intel N100 mini PC and a Raspberry Pi 5 on the same network.
- A heartbeat. Every 10 seconds each machine sends a small record: a sequence number, when it was sent, when its process started, CPU load, available memory, temperature, and how many heartbeats it failed to send. Each machine also keeps its own copy on disk, in case the link is what fails.
- A collector on the N100 that stores what arrives, with the arrival time. Both machines send to it, the N100 to itself.
- A detector that runs once, at 6:30 a.m., over the whole night (10 p.m. to 6:30 a.m.) with fixed rules. It writes a JSON file with every incident: start, end, duration, when it was detected, whether it recovered on its own, and the evidence.
- A writer. Gemma 3 4B in Ollama reads only that JSON and writes the morning report in Markdown. It does not decide whether something failed. That was decided before it woke up.
Each machine writes its own report from the same JSON: the N100 at 6:30, the Pi at 6:40. That lets me compare an x86 mini PC and an ARM board doing the same job with the same model. One known gap: everything goes through the N100, so if the N100 is down, there is no report.
Demo
This is part of the Pi’s report after a night with eight injected faults, exactly as Gemma wrote it (the prompt is in Spanish; lines wrapped, two of the eight incidents shown):
# Turno de noche: 2026-10-21 22:00
**Salud general:** mala. El 99.9% de los latidos recibidos provienen del
equipo N100, mientras que el 87.2% provienen del Raspberry Pi 5.

## Incidentes
*   **N100:** servicio reiniciado, 22:39:51 - 22:40:30, 39 s, detectado
    22:40:21, no confirmado
    Hechos observados: Ningún latido recibido de 22:39:51 a 22:40:30 (39 s;
    se esperaba uno cada 10 s). El latido siguiente viene de un proceso
    nuevo, arrancado a las 22:40:30. El vigilante del equipo registró la
    caída del proceso a las 22:40:00 (código -15). / Posibles explicaciones:
    Fallo en el sistema operativo. / Causa confirmada: no confirmada
*   **Raspberry Pi 5:** el equipo no envió, 23:29:51 - 23:35:01, 310 s,
    detectado 23:30:21, no confirmado
    Hechos observados: Ningún latido recibido de 23:29:51 a 23:35:01 (310 s;
    se esperaba uno cada 10 s). El mismo proceso antes y después; faltan 30
    latidos en la secuencia. El propio equipo registró 30 latidos como no
    enviados en ese lapso. / Posibles explicaciones: Problema de red. /
    Causa confirmada: no confirmada
Translation. Night shift: 2026-10-21 22:00. Overall health: bad. 99.9 % of the heartbeats received come from the N100, while 87.2 % come from the Raspberry Pi 5.
N100: service restarted, 22:39:51–22:40:30, 39 s, detected 22:40:21, not confirmed. Observed facts: no heartbeat received from 22:39:51 to 22:40:30 (39 s; one expected every 10 s). The next heartbeat comes from a new process, started at 22:40:30. The machine’s watchdog logged the process going down at 22:40:00 (code -15). Possible explanations: operating system failure. Confirmed cause: not confirmed.
Raspberry Pi 5: the machine did not send, 23:29:51–23:35:01, 310 s, detected 23:30:21, not confirmed. Observed facts: no heartbeat received from 23:29:51 to 23:35:01 (310 s; one expected every 10 s). The same process before and after; 30 heartbeats missing from the sequence. The machine itself logged 30 heartbeats as unsent in that span. Possible explanations: network problem. Confirmed cause: not confirmed.
The observed facts are right. Several things around them are wrong, and finding them is what this post is about.
Code
Everything that ran is in github.com/israel0negrete-crtdrops/night-shift, MIT licensed: heartbeat, watchdog, relay, collector, detector, writer, fault injector, fault plans and checker, all standard-library Python plus Ollama. It is the code exactly as it ran on these nights, not a cleaned-up version: the files on both machines match the repository byte for byte. It also has the raw heartbeats of the two fault nights; replaying the detector on them gives exactly the same JSON, and the writer can be replayed on any of the nights.
I built it with Claude Code as a pair: I decided what to measure, what the lab could and could not be put through, and what the report had to say; Claude wrote most of the code and ran it on the machines with me.
How I built it
Why the model does not read the logs
The first version was the obvious one: give Gemma the last 40 warnings from the N100’s journal and ask for two lines. I gave the same 40 to both machines.
Both took about 2 minutes, wrote a paragraph instead of two lines, and described the desktop’s background noise (GNOME, PipeWire, a keyring) as “system instability”; one recommended investigating it. On a desktop machine most warnings are not failures, and the model has no way to know which ones are.
So the job got split. Rules decide what happened; the model only puts it into words. The detector is under 200 lines. And to know whether the rules were right, I needed nights where I knew exactly what had failed and when.
Three fields that make a gap readable
The sequence number, the process start time and the machine’s own count of what it failed to send. A new start time after a gap means the process restarted. The same process with missing sequence numbers means heartbeats went missing. And if the machine itself counted them as unsent, they never left; if it did not, they left and never arrived. Without those three fields, all of these look like the same hole in the chart.
Nights with known faults
Two quiet nights first, with no faults, as a baseline. Then two nights with eight controlled faults each, injected by a script at fixed times and logged with their real start and end; the second night moved each fault to the other machine and to another hour:
| Fault | What it does | What the detector should say |
|---|---|---|
| Interruption | kills the heartbeat process; a watchdog restarts it 30 s later | service restarted |
| Silence | the process stays alive but stops sending | the machine did not send |
| Cut | the relay drops that machine’s heartbeats | heartbeats lost on the way |
| Latency | the relay delays them 3–5 s | latency |
| CPU | four busy processes on four cores | CPU saturation |
| Memory | holds memory until 15 % is left | low memory |
| Pause | stops the process until after the window closes | no heartbeat, unresolved |
Most faults touch only the experimental flow. CPU and memory put bounded load on the machine itself: the CPU fault stops at a temperature limit, and the memory fault never leaves less than 600 MB. No reboots, no changes to the machines’ real network, no production service stopped.
A checker for the writer
A script compares each report with the JSON it was given. It looks for incidents left out, times and figures that are not in the JSON, causes stated as confirmed, adjectives like “high temperature” with no incident behind them, incidents invented on a quiet night, and a missing or invented comparison with the previous night. The real fault log grades the detector, not the report.
The checker runs on my laptop, not in the lab, and it misses things. Most of what is wrong in the demo above I found by reading the reports.
Results: detection
| Night | Faults injected | Detected | False alarms | Detection delay |
|---|---|---|---|---|
| Quiet 1 | 0 | 0 | 0 | — |
| Quiet 2 | 0 | 0 | 0 | — |
| Faults, night 1 | 8 | 8 | 0 | 21–30 s; CPU 111 s |
| Faults, night 2 | 8 | 8 | 0 | 20–30 s; CPU 112 s |
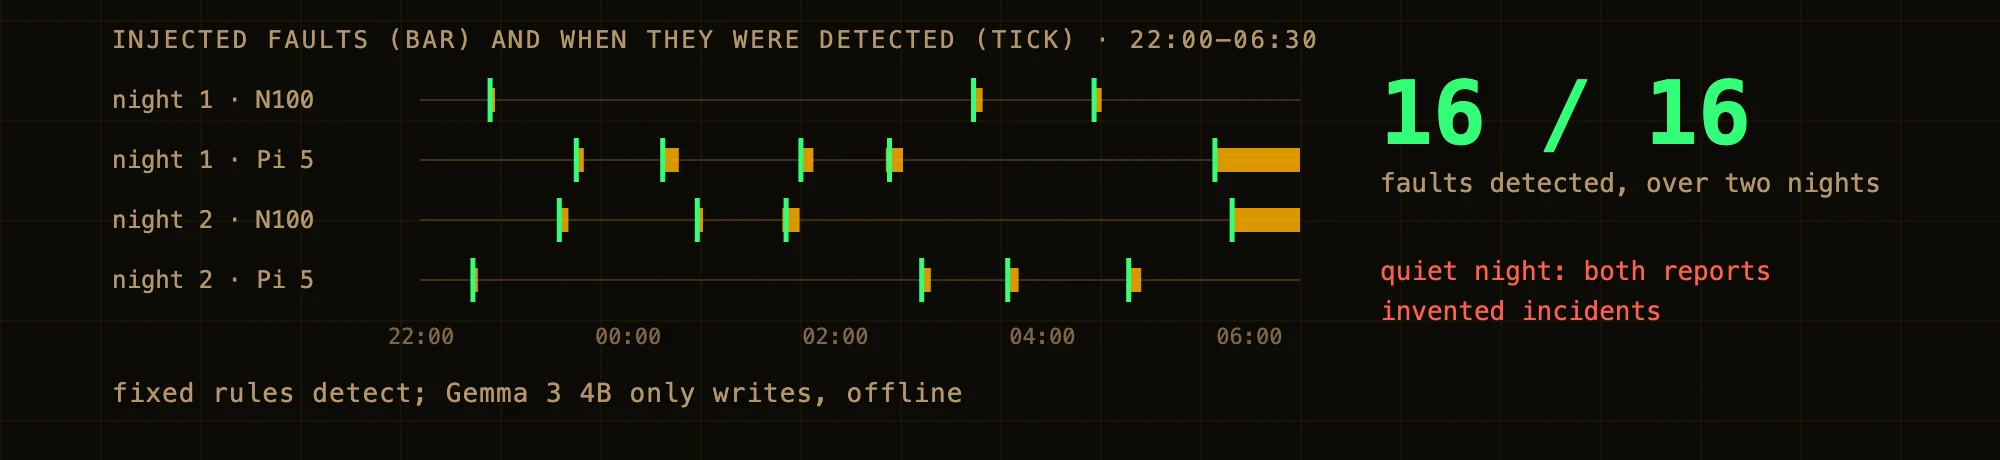
On the quiet nights, 3,060 of 3,060 heartbeats arrived from each machine. With faults, the rules found all sixteen, each with the right type. The last fault of each night, a pause that runs past 6:30, came out as unresolved, which is correct.
The second night also had an incident nobody planned. The CPU fault pushed the N100 to 84 °C, over the 80 °C rule, for 50 heartbeats, and the detector reported high temperature. My checker counted it as a false alarm because it was not in the plan, but the temperature really did cross the line: it is a side effect of the fault, and the rule was right to catch it.
The detector runs once, at 6:30, so “detected” is when the rule would have fired, reconstructed from the data, not a live alert. The CPU fault shows up late because the one-minute load average needs about a minute and a half to pass 3.0 (75 % of four cores), plus 20 seconds for the rule’s three heartbeats in a row.
The detection is boring, and it should be.
Results: what Gemma wrote
On the first quiet night, both machines invented incidents. The JSON said zero incidents. Each report listed one per machine anyway, built from that machine’s peak temperature (73 °C on the N100, 50.1 °C on the Pi, no rule fired), gave them a duration of “00:30” that appears nowhere in the data, and recommended checking the temperature or the ventilation. A quiet night is exactly when a summarizer is tempted to find something to say.
On the second quiet night, the Pi correctly wrote that there were no incidents, but left out the comparison with the previous night, which was in the JSON. The N100 included the comparison but listed normal readings under “Incidents”. And both put the start of the night in the title (2026-10-20 22:00) instead of the morning date the template asks for.
On the first fault night, it got the structure and most of the numbers right. Neither machine left out an incident or stated a cause as confirmed, and the checker found no time or figure that is not in the JSON. But the checker only looks for numbers that appear nowhere in the JSON, and that is how the worst error got through:
- The Pi invented a fact with a real number. For the last incident, the pause still open at 6:30, it wrote that “the machine itself logged 30 heartbeats as unsent in that span”. That sentence belongs to the silence incident six hours earlier. The JSON gave this incident two facts, and the Pi dropped one of them: that no heartbeat had arrived by the end of the window. It could not even be true, because the pause kills the heartbeat process, so nothing was counting. The 30 passed the checker because 30 appears elsewhere in the JSON.
- The health line misreads the numbers. 99.9 % and 87.2 % are the share of each machine’s own heartbeats that arrived, not where the heartbeats came from.
- The possible explanations contradict the evidence. The Pi logged its 30 heartbeats as unsent, so they never reached the network; the real cause was the silence fault, and “network problem” is ruled out by the facts two lines above. The N100’s process was stopped with a normal termination signal (code -15), which is not an operating system failure.
- “Not confirmed” where the template asks whether it recovered on its own. The JSON said it did.
The checker did catch one: the Pi skipped the comparison again, and this time so did the N100, writing that there was no previous night to compare while the JSON carried its figures. The rest is smaller: the N100 reduced each incident to one generic line (“The N100 restarted the service.”) and dropped the evidence, the Pi wrote “null” for the end of the incident still open at 6:30, and both titles carried the start of the night again.
On the second fault night, both machines swapped two incidents between machines. The 22:29 interruption was the Pi’s, and both reports put it under the N100; the 23:20 latency was the N100’s, and both put it under the Pi. Same mistake on x86 and on ARM, and the checker cannot see it, because both machine names are in the JSON. The N100’s health line also gave the Pi 87.2 %, which was the previous night’s figure, copied from the comparison block; that night the Pi had 98.5 %. It wrote 23:40:22 as the detection time of an incident detected at 00:40:22, which the checker did catch. And both skipped the comparison once more: three nights in a row for the Pi.
Same model, same JSON, same prompt, temperature 0 and seed 42 on both machines, and the text still came out different on each. At temperature 0 the seed barely matters; what differs is the arithmetic. The x86 and ARM builds round slightly differently, and one different token changes everything after it. I did not test repeat runs on the same machine, so I cannot say that pinning the hardware is enough, only that pinning the model is not.
N100 or Pi 5?
| N100 | Raspberry Pi 5 | |
|---|---|---|
| Report with 8 incidents | 294.8 s | 468.8 s |
| Reading the prompt (2,565 tokens) | 20.7 tokens/s | 26.3 tokens/s |
| Writing the report | 5.7 tokens/s (934 tokens) | 3.3 tokens/s (1,199 tokens) |
| Report on a quiet night | 86–128 s | 76–101 s |
On the second fault night it was 303.4 s on the N100 and 520.9 s on the Pi. The Pi reads faster and writes slower, and with faults it also writes more, because it copies the evidence that the N100 drops. Three tokens per second sounds slow, and at 6:40 a.m. it does not matter: nobody is waiting, and both reports are ready well before 7. Slow and steady is enough for a night shift.
Why does open innovation matter?
- The logs never leave the lab. Ollama listens on 127.0.0.1. Nothing about my machines goes to anyone else’s server, and the night shift keeps working if the internet does not.
- It costs nothing per night. No tokens to pay for, no key to rotate. It runs on hardware that was already on.
- I can pin it. The model is
gemma3:4b, id68ceab7e468a, Q4_K_M, with temperature 0, seed 42 and an 8,192-token context, on Ollama 0.40.6. A hosted model can change under you between one night and the next; this one only changes when I change it. That matters when the point is to measure it. - I can run the same model on x86 and on ARM and see the difference, which is how I found that the same settings do not give the same text on two processors.
To be precise about “open”: Gemma’s weights are open under the Gemma Terms of Use, not an OSI license; Ollama is MIT. What matters here is that both run entirely on my machines.
The lazy payoff
Nobody has to open logs in the morning: read the health line, and if it is not “good”, the incidents under it. The health word comes from the detector’s JSON; Gemma copied it correctly every night, but that is Gemma copying, not a guarantee, so the next change is to have the detector write that line itself.
What I do not do is trust the report alone. The rules decide, I run the checker over what the model wrote, and its explanations are treated as guesses, because the fault night showed they can contradict the facts right above them. It has run for five nights, not months, and that is what five nights showed.
Israel Negrete Lepe is an electronics engineer. Twenty-five years making different systems work together under real conditions: from the sensor, the vehicle or the transaction to the backend, the data, security and operations. Today, increasingly, edge AI.